
AI agents used to be the digital equivalent of a parrot: you said a phrase, it repeated it, you nodded. Now they are overcaffeinated interns who can read the file, call the tool, summon a coworker, and somehow remember that you mentioned the password was ‘pineapple’ three meetings ago.
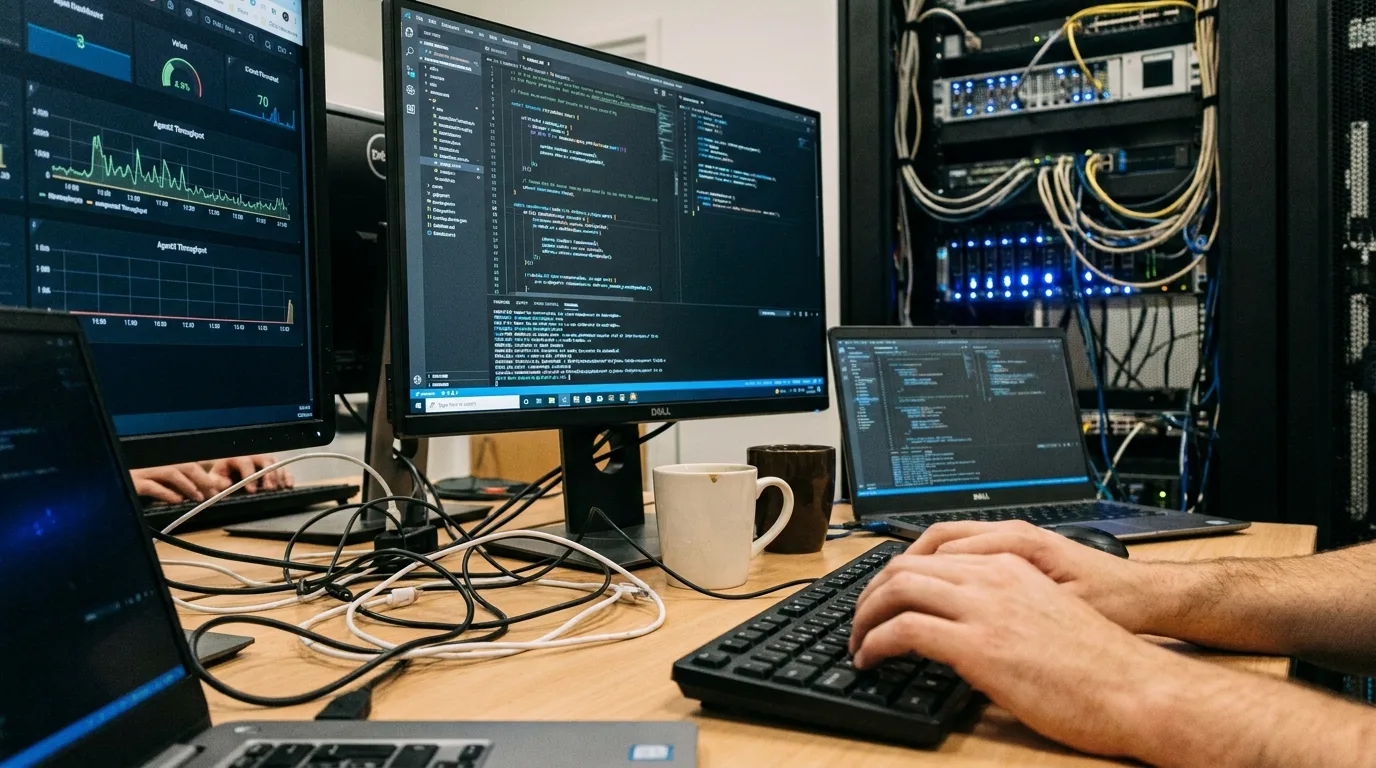
That shift changes everything. A single request used to be a short conversation; now it is a workflow. Agents reason, invoke tools, coordinate subagents, and drag a growing context with them like a suitcase stuffed with receipts. The scale is not imaginary. OpenRouter’s State of AI report found that, across 100 trillion tokens of real-world usage, average prompt tokens per request grew about fourfold. A single agentic request can consume 15 times the tokens of ordinary chat. My own experience mirrors the math: I once asked a coding agent to fix a tiny bug, and it turned my afternoon into a scavenger hunt through logs, APIs, and one very suspicious config file.
But measuring this new workload is tricky. A benchmark cannot simply ask, “How fast can you answer a 1K-word question?” It needs to capture long-context prefill, KV-cache reuse, interactive decoding, tool-call gaps, and distributed mixture-of-experts execution under real concurrency. It also has to show how much of a data center’s power budget becomes useful agentic throughput without making users feel like they are waiting for soup to cool.
Enter SemiAnalysis AgentX, part of the InferenceX suite. AgentX replays prerecorded Claude Code sessions, preserving their messy rhythm: long contexts, repeated context reuse, reasoning pauses, and tool-call interruptions. The same traffic hits every system, so the score reflects the serving stack, not clever tuning. The metric that matters for AI factories is tokens per megawatt, reported alongside interactivity, end-to-end latency, and time to first token.
The results read like a sequel nobody asked for. NVIDIA’s GB300 NVL72 already shows a big leap: up to 15x higher AI-factory throughput per megawatt than H200 NVL8 on DeepSeek V4 Pro, and up to 10x lower cost per million tokens. On Kimi K3, the gap grows to roughly 80x higher throughput per megawatt at comparable interactivity. That is not just a lab curiosity; it means the same power budget can serve more interactive agents, or serve the same agents cheaper.
Then there is Vera Rubin NVL72. NVIDIA measured it with AgentX, and at 160 tokens per second per user, it delivers up to 30x higher AI-factory throughput per megawatt than GB300 NVL72. The broader Rubin platform pairs Rubin GPUs with Vera CPUs for tool execution and cache offload, while networking and scheduling pieces move context around so agents stop repeating themselves like a group chat nobody left.
The point is not that AI became bigger. It became longer, messier, and more useful. Benchmarks like AgentX give us a way to ask the right question: can your AI factory keep pace with the intern, the tool, the cache, and the user all at once? It turns raw watts into patient, useful, surprisingly good, human-ish daily assistance.
The AI Intern Who Ate My Lunch?
 Newsletter: FIRST RULE OF INTELLIGENT AUTOMATION: DON’T AUTO…
 Newsletter – Where Does Your Data Go?
 Episode 40: Supercharge Your Sales with AI Lead Scoring
 Build Versus Buy: How AI Is Upending Business Software
 Accountancy Newsletter: So, how did August 7, the first MTD …
 Accountancy Newsletter: So, how did August 7, the first MTD …
 Inside the AI Research Kitchen When Coding Agents Start Doin…
 Episode 39: Knowledge Management Reimagined: Cure Corporate …
 Episode 38: The AI Product Manager: Your Most Important Hire
 Accountancy Newsletter: So, how did August 7, the first MTD …