
I wanted a portfolio project that showed multi-agent design without pretending a single chatbot with a pretty wrapper was the whole crew. So I built PR Review Crew, a six-agent GitHub reviewer that runs on free, open-source ChatDev 2.0. Point it at a PR, and six agents fetch the diff, review it from different angles, merge their opinions, and post one tidy comment back to GitHub.
In theory, it was a small production system wearing a lab coat. In practice, it was a six-person team where one member read the same success message forty-three times and kept saying, “Maybe I should try again.”
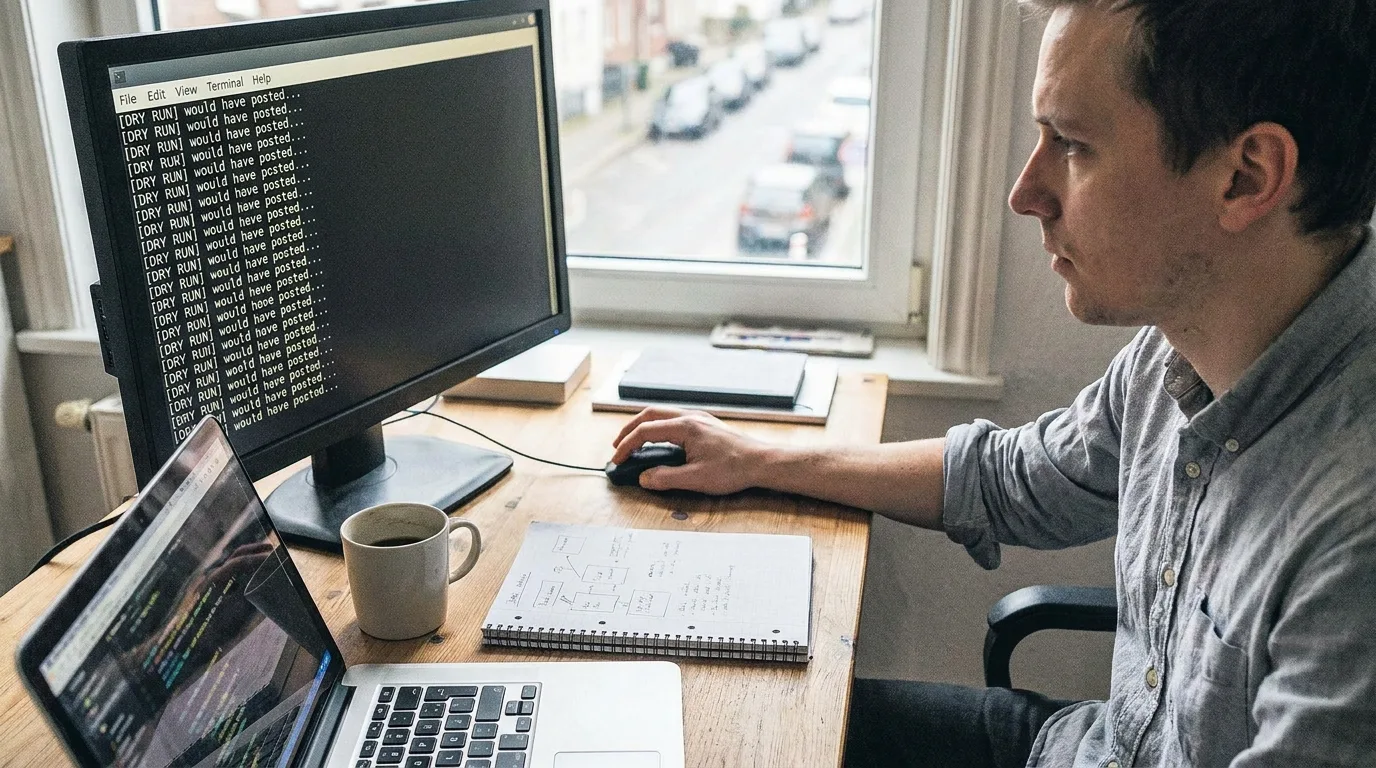
That bug became my favorite anecdote. Comment Poster had called its tool once, successfully. Then the model saw its own result, apparently thought, “Well, better call it again to be sure,” and kept looping. The runtime log looked like a broken elevator: [DRY RUN] would have posted… over and over, with token count climbing like rent. There was no code mistake in my prompt. ChatDev gives each agent node an implicit self-loop after a tool call, feeding the result back so the model can decide whether to stop. Mine decided not to, for a long time.
The fix was insultingly simple: tell it that past success means stop. “If the conversation already contains a result from postreviewcomment, do NOT call it again.” Obvious after the fact. Not obvious when your free-tier quota is evaporating like cold coffee.
I hit four other bugs while staying free. A small model garbled a yellow circle emoji into an invalid JSON escape because small models are bad at copying exact weird Unicode. A token limit was too modest for a full review hidden inside a tool-call argument, so the JSON stopped mid-brace like a sentence abandoned by its author. A tool result echoed too much text, doubling a review body and pushing the request past Groq’s cap. Each bug was tiny, but together they were a gauntlet.
This is where a relatable personal experience lives: I once spent an afternoon debugging a script that worked perfectly until I changed the working directory, then realized my shell history had taught me to blame everything for everything. Agentic pipelines do the same. A model, a token limit, a tool result, and a GitHub permission can sound like the culprit while the real problem is one line too far.
Later, a reasoning model reasoned itself into silence. It spent its output budget thinking and returned an empty answer, like a coworker who attended the meeting but contributed nothing. Raising the budget helped sometimes. Capping reasoning effort helped reliably. The final 403 was not about token scope but about a fine-grained GitHub token that did not know my brand-new demo repository existed.
The throughline? Small models need lean payloads at every hop. The lesson was not “use bigger prompts” but “watch every object crossing the room.” If your reviewer calls its own tools forty-three times, maybe it needs a stronger stop sign and less anxiety.
When My Code Reviewer Started Calling Its Own Tools Like a Very Eager Intern
 Newsletter: FIRST RULE OF INTELLIGENT AUTOMATION: DON’T AUTO…
 Newsletter – Where Does Your Data Go?
 Episode 40: Supercharge Your Sales with AI Lead Scoring
 Build Versus Buy: How AI Is Upending Business Software
 Accountancy Newsletter: So, how did August 7, the first MTD …
 Accountancy Newsletter: So, how did August 7, the first MTD …
 Inside the AI Research Kitchen When Coding Agents Start Doin…
 Episode 39: Knowledge Management Reimagined: Cure Corporate …
 Episode 38: The AI Product Manager: Your Most Important Hire
 Accountancy Newsletter: So, how did August 7, the first MTD …