Hello and welcome back to the blog! It’s great to have you here for another episode of AI Solutions: The Pathway to Profit.
You know, after spending years in this space, I’ve noticed something fascinating. I’ve seen countless companies launch impressive AI features, but only a handful manage to create a truly lasting, dominant advantage. What separates the leaders from the followers? It’s not just about having the smartest algorithm or the biggest initial dataset. It’s about harnessing one incredibly powerful concept we’re going to explore together today: Building a Data Flywheel.
This isn’t just another buzzword; it’s the beautiful, self-reinforcing engine that explains why companies like Amazon, Google, and Tesla don’t just win—they build almost unbeatable moats around their businesses. These moats get deeper and wider with every single user interaction, every single day. So, let’s roll up our sleeves and get into it.
What Exactly Is an AI Data Flywheel?
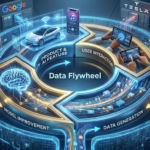
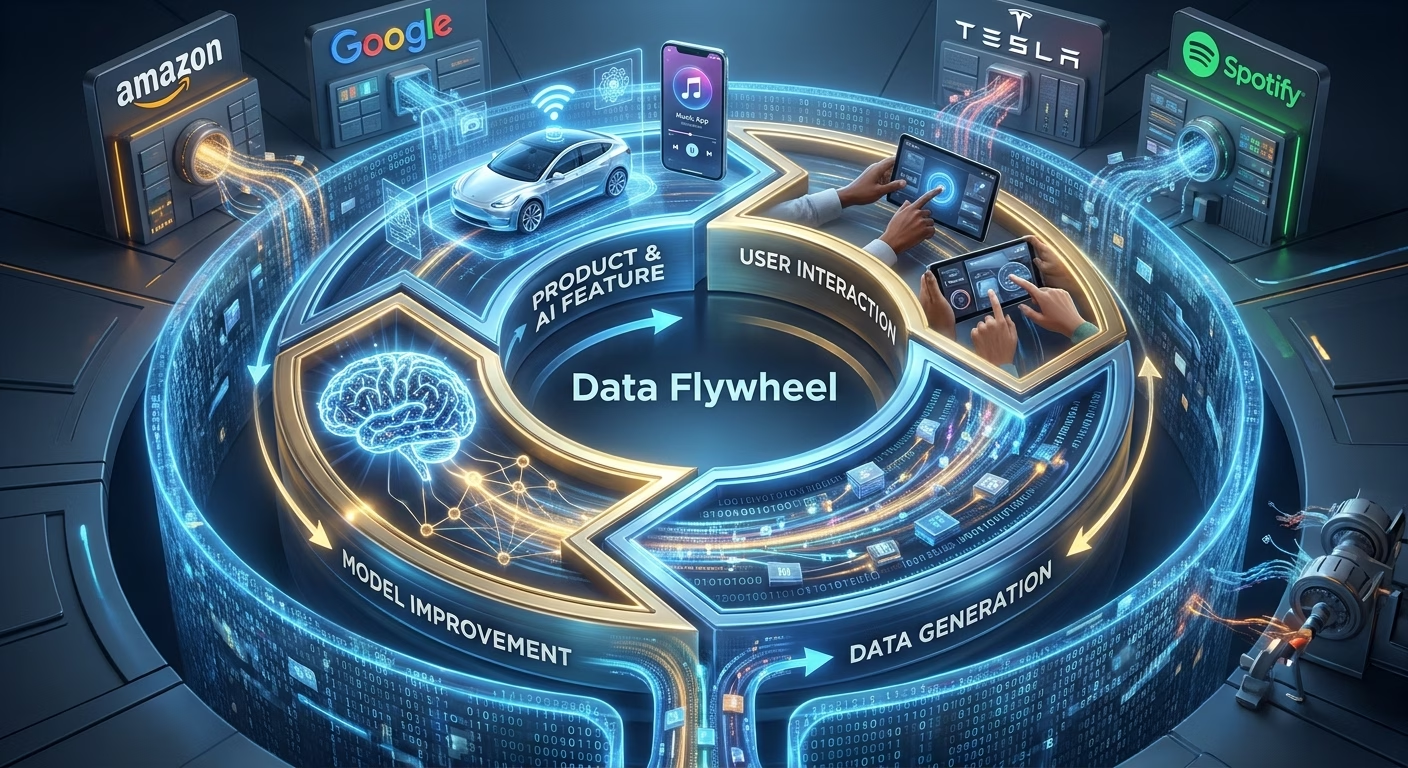
So, what is a “Data Flywheel” when we talk about AI? Let me paint a vivid picture for you. I want you to imagine a simple but powerful four-stage engine. It’s not complex, but its effects are profound:
- Stage 1: The Product. You launch a product or a feature powered by your AI model. It’s out in the world, ready to provide value.
- Stage 2: User Interaction. Your users begin to interact with it. This is the magic moment, the point where potential energy becomes kinetic.
- Stage 3: Data Generation. These interactions generate a continuous, beautiful stream of new, unique data. This isn’t just any data; it’s the fuel for your engine.
- Stage 4: Model Improvement. We take this fresh data and feed it back into our AI model to retrain and improve it. This makes the product itself smarter, more accurate, and more useful.
And here’s where the cycle truly begins to accelerate. A better product attracts more users. More users generate more data. More data creates an even better model. The wheel spins faster and faster. It’s a learning loop that becomes exponentially more intelligent with every rotation. This is where that incredible compounding advantage starts to form.
The Flywheel in Action: Real-World Titans
This might sound a bit abstract, so let’s look at a prime example that brings this principle to life in the physical world: Tesla’s Autopilot.
The product, of course, is the driving-assist feature. But the flywheel starts spinning the moment a driver gets behind the wheel. We’re talking about millions of Tesla owners driving billions of miles. Every one of those miles is a data point. Every turn, every stop, every unexpected swerve to avoid a deer—it’s all captured.
This generates a massive, and more importantly, fundamentally proprietary dataset of real-world driving scenarios. It captures all the strange, unpredictable moments—what we call “edge cases”—that are so crucial for training a truly robust system. A competitor can’t just buy this data; it’s born from the collective experience of the entire Tesla fleet.
Tesla then feeds this river of data back into its neural networks. The AI learns. It improves. Then, through those slick over-the-air updates, the entire fleet gets smarter. A better, safer car is more desirable, which sells more cars, which puts more sensors on the road, gathering even more data. You see the cycle? It’s breathtaking.
Now, let’s move from the physical world of cars to the digital realm of music. Another beautiful example, and one I think we can all relate to, is Spotify’s recommendation engine.
The product here isn’t just playing music; it’s features like your Discover Weekly playlist or the daily mixes it curates just for you. Every time you listen to a song, skip one, save it to a library, or share it with a friend, you are spinning that flywheel. You’re teaching the machine.
But here’s where it gets truly elegant. This data doesn’t just tell Spotify what you like. It reveals these hidden, almost quantum-like connections between songs and listeners across their entire global network. It learns that people who like Artist A on a rainy Tuesday also tend to like Artist B. This is the deep insight that trains their algorithms to become so uncannily accurate—to predict what you want to hear before you even know it yourself.
The better the recommendations, the longer you listen and the more you feel the service “gets” you. This generates more data, which makes the recommendations even better, and the flywheel spins faster, making the service feel almost indispensable.
The Unbeatable Advantage: Your Competitive Moat
This brings us to the quiet, strategic power of the data flywheel. My favorite way to think about it is that it creates a competitive moat. A deep one.
It’s not about having “big data,” a term that gets thrown around so much it’s almost lost its meaning. The real power is in having proprietary data—data that is born from the unique interactions your users have with your product.
Let’s imagine a challenger wants to take on Spotify. They can’t simply purchase a massive dataset and catch up. It doesn’t work that way. They have to start from absolute zero. They have to build a competing product, somehow attract a critical mass of users (who are already happy with Spotify’s amazing recommendations!), and then begin the slow, arduous process of getting their own flywheel to turn.
By the time they are just beginning to spin, the leader’s flywheel has incredible momentum. Their product is already so far ahead that the gap is no longer a gap. It has become a chasm. This is the beauty of it. The advantage compounds, relentlessly, over time.
How to Give Your Flywheel Its First Push
Okay, so the question you’re probably asking is, “This sounds amazing, but how do I actually start one?” How do you give that first, deliberate push to your own flywheel?
My process always starts with these three critical steps:
- Find the Core Value Loop: This is job number one. You need to find that point of perfect resonance where an AI feature provides genuine, undeniable value to a user, and in that very same action, it generates the precise data you need to improve. For Tesla, it’s driving. For Spotify, it’s listening. What is it for you?
- Solve the ‘Cold Start’ Problem: When you begin, you have no user data. This is the classic chicken-and-egg scenario. So, how do you get the model good enough to attract those first users? You can start with publicly available datasets, or—and this is a truly elegant solution I love—you can generate synthetic data to seed your model. Another great approach is to start with a “human-in-the-loop” system, where a person guides and corrects the AI in its infancy, teaching it the ropes.
- Build the Data Pipeline: This is absolutely critical, and it’s where I see a lot of projects stumble. You must build the automated plumbing—the circulatory system—that collects, cleans, and feeds this new user data back into your model retraining process. Without an automated flow, your flywheel has no energy. It simply cannot begin to spin on its own. It becomes a manual, clunky process, not a self-reinforcing loop.
A Word of Warning: The Dangers in the Spin
Now, as powerful as this system is, I have to be honest with you. It isn’t a magic button. This beautiful, self-reinforcing system requires careful observation, because it isn’t without its dangers.
A painfully common pitfall is bias amplification. If your initial data carries a bias—and almost all real-world data does—the flywheel will not magically fix it. In fact, it will do the exact opposite. It will reinforce and magnify that bias with every single rotation. This can create a negative feedback loop where the product actually gets worse for certain groups of users, potentially alienating them entirely.
And then there are the ethical considerations, which are paramount. My unbreakable rule here is radical transparency with users. You have to help them understand what data you’re collecting and clearly articulate how it’s being used to improve their experience. User trust is the essential lubricant for this entire system. If you break that trust, it’s like throwing a wrench right into the gears. The whole thing will grind to a halt.
Your Strategic Imperative
So, to bring it all together, I want you to see the data flywheel not as a mere tactic, but as a strategic imperative for long-term success with AI. It’s the mechanism that transforms a single, static AI model into a living, learning, self-improving system.
It’s that beautiful, elegant loop:
Better Product ➔ More Users ➔ More Data ➔ Smarter Models ➔ Even Better Product
It’s a journey, not a destination. It requires thoughtful design, a deliberate first push, and careful stewardship to keep it spinning true. But once it gets going, its momentum can become the single greatest asset your business has.
I hope this has given you a clear framework for thinking about how to build a lasting competitive advantage with AI. But as we’ve explored, this system requires careful management of both the data and the models. Which leads to a natural, and rather important question… what happens when AI use isn’t managed?
That’s precisely what we’ll be exploring in our next episode, “The ‘Shadow AI’ Problem: When Employees Use Unauthorized AI Tools.” We’ll dive into the hidden risks, and perhaps the surprising opportunities, that arise when AI goes rogue within an organization.
Thank you so much for tuning in. As always, I love hearing from you, so please drop your questions or thoughts in the comments below! Talk to you next time.